Practical AI: Turning Everyday Work Into Better Decisions
A grounded guide to introducing AI where it improves clarity, service and human decision-making.
A grounded guide to introducing AI where it improves clarity, service and human decision-making.
This long-form guide is designed as a working resource rather than a generic trend report. Its visual model, operating questions and practical framework are specific to artificial intelligence. Use the evidence as a prompt for discussion, then replace the illustrative figures with a baseline drawn from your own context.

Use this visual as a prompt for discussion: what changed, who benefits, which assumption needs testing, and what evidence would make the next decision safer? A mature team does not treat an image or chart as decoration. It asks what the visual makes easier to notice, what it leaves out, and whose experience should be added before a decision is made. Record the interpretation beside the metric, test it against a real example, and revisit it when the context changes. This simple practice turns a polished article into a useful working session.
Choose a decision worth improving
AI creates value when it improves a decision, not merely when it produces text quickly. Write down the decision, the evidence normally used, the accountable person, and the cost of a poor answer. A useful pilot may classify support requests, summarise case history, or draft from approved guidance. The reviewer still owns the outcome; the system makes relevant context easier to see.
Build an evaluation set before launch
Collect representative examples before tuning prompts or choosing a vendor. Include routine requests, ambiguous language, incomplete records, sensitive topics, and cases where experts disagree. Define what a good response must contain and what it must never do. Run meaningful changes against the same set so the team can distinguish reliable progress from a polished demonstration or one fortunate example.
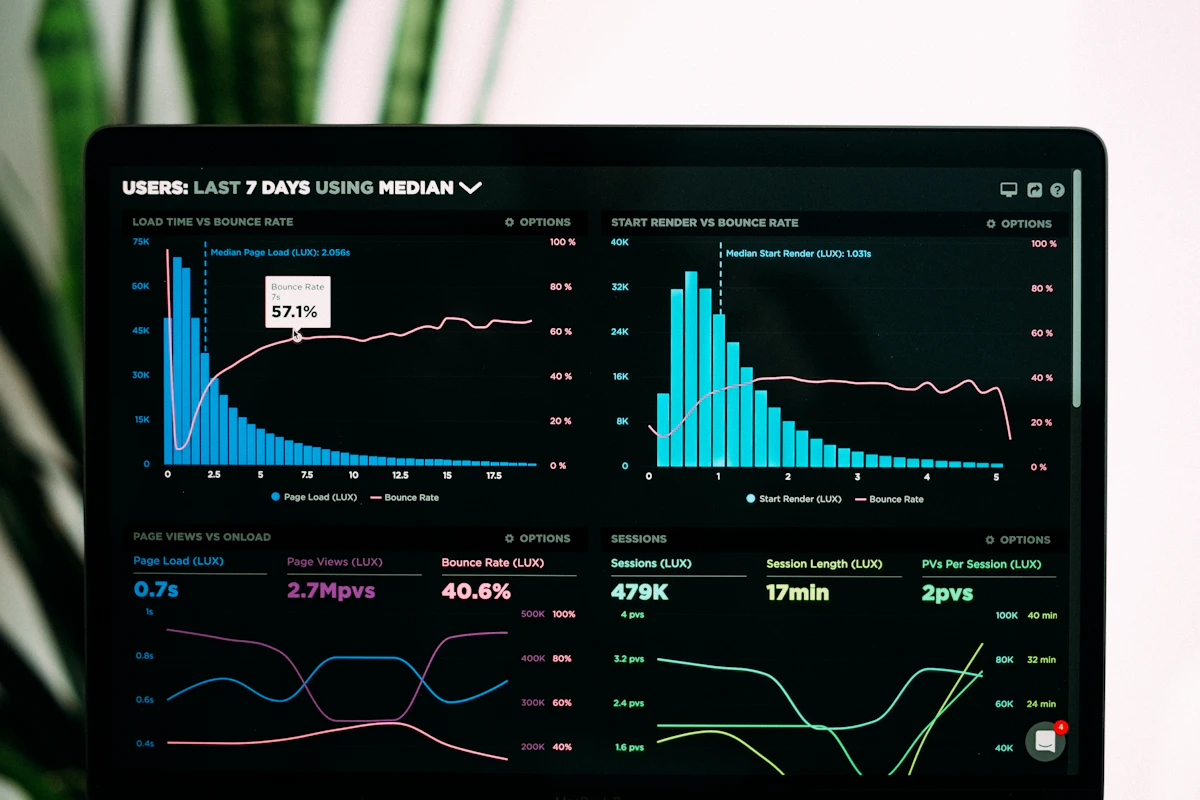
Use this visual as a prompt for discussion: what changed, who benefits, which assumption needs testing, and what evidence would make the next decision safer? A mature team does not treat an image or chart as decoration. It asks what the visual makes easier to notice, what it leaves out, and whose experience should be added before a decision is made. Record the interpretation beside the metric, test it against a real example, and revisit it when the context changes. This simple practice turns a polished article into a useful working session.
Measure the whole workflow
Time saved is only one signal. Track acceptance, correction effort, resolution quality, repeat usage, escalations, and satisfaction together. Review samples of successes as well as failures because a plausible answer can conceal an omission. Segment results by request type and user group. Averages often hide the edge case that matters most; a balanced scorecard makes trade-offs visible.
Create calm governance
Record the purpose, approved data sources, access rules, model and prompt changes, evaluation results, and the owner who can pause the workflow. Review high-impact uses more often than low-risk drafting. Give staff a clear route for reporting problems without blame. Governance should make responsible experimentation easier by replacing uncertainty with visible boundaries, evidence, and timely decisions.
An AI decision-control matrix
The upward line is not a promise of automatic improvement. It represents a team expanding its evaluation set, clarifying review rules and correcting weak source material. Watch correction effort alongside acceptance: if acceptance rises only because reviewers stop checking, the metric has lost its meaning.
| AI use case | Human checkpoint | Primary metric | Stop condition |
|---|---|---|---|
| Request classification | Review low confidence | Routing accuracy | Sensitive cases misrouted |
| Case summary | Verify source record | Correction effort | Material facts omitted |
| Response drafting | Approve before send | Resolution quality | Unsupported claim |
| Knowledge retrieval | Open cited source | Evidence coverage | Source access failure |
From pilot to practice
The first version of a workflow is a learning instrument. Expect questions that were not visible in the brief: who is left out, which exception takes the most time, and which small choice changes the outcome. Capture these questions beside the metric. A number tells you what moved; a note from a person often explains why.
Move from individual heroics to repeatable service. Document decision rules, handoff points and the language people use when something goes wrong. Make the next step obvious for a new team member. This is how an organisation grows without making every improvement depend on one expert remembering everything.
Make the invisible work visible
Every polished result has a hidden operating cost: reviewing, correcting, explaining, supporting and maintaining. Count that work honestly. When it is visible, leaders can decide whether to simplify a promise, improve a tool or allocate capacity. Invite the people closest to the work into design and review, pair their knowledge with analytics, and make a decision both can support.
Turn insight into a responsible pilot
Begin with a one-page brief. Name the human outcome, the people affected, the current experience, the decision owner and the evidence that would justify continuing. Choose a pilot that can be reversed without harming the people it is meant to serve. Establish a baseline before changing the workflow, including ordinary examples, difficult edge cases and stories that explain why the numbers look as they do.
- Define: describe success in language a participant recognises.
- Observe: measure the current journey before introducing a solution.
- Experiment: change one meaningful element and assign an owner.
- Review: inspect quality, adoption, accessibility and unintended effects.
- Decide: scale, revise or stop based on recorded evidence.
Read analytics with context
A dashboard is a conversation starter, not a verdict. Write the operational question beside every metric and identify who can act when it moves. Compare trends over time, segment results where fairness or access may differ, and annotate releases, events or policy changes that could explain a shift. Pair quantitative signals with interviews and reviewed examples. Numbers reveal patterns; people often reveal the mechanism behind them.
Do not compress the scorecard into one success number. A faster process with lower confidence is not automatically an improvement; neither is high participation if the same group carries all of the hidden support work. Agree thresholds before results arrive, record interpretation beside the chart and keep a decision log. This preserves organisational memory and makes later changes easier to explain.
Make invisible work visible
Every polished service has an operating cost: reviewing, correcting, welcoming, explaining, supporting, securing and maintaining. Count that work honestly. When it is visible, leaders can simplify a promise, improve a tool or allocate capacity before goodwill becomes burnout. Invite the people closest to the work into design and review. Their experience is essential evidence about exceptions, language, trust and the real effort required.
A 30-day field guide
Week one: listen and baseline
Observe the journey without rushing to solve it. Interview a small, varied group, review recent examples and document the current time, quality, handoffs and failure demand. Confirm what must not change. End with a shared problem statement and an owner who has authority to make a decision.
Week two: prototype safely
Create the smallest end-to-end version that can teach the team something. Use appropriately protected information, make limitations visible, provide a manual path and rehearse what happens when the system is wrong or unavailable. Accessibility and privacy belong in the prototype because they influence the shape of the service.
Week three: learn in real conditions
Run with a limited group and short feedback loops. Review examples together instead of relying only on aggregate analytics. Log surprises, corrections, support effort and emerging risks. Communicate what is experimental and how participants can reach a person. Change one variable at a time where practical so the team can understand cause and effect.
Week four: decide and document
Compare the evidence with the thresholds in the original brief. Decide to scale, revise, pause or stop, and explain why. Document the operating owner, review cadence, access rules, training, incident route and next evaluation date. A stopped pilot can be a success when it prevents a weak idea from becoming an expensive dependency.
Premium technology is the calm, dependable layer that helps people make better decisions and leaves them with more agency.
A practical operating playbook
Start with a written brief: the decision to improve, the people affected, the available data and the measure that will show whether the change works. Choose a responsible experiment, give it an owner, measure quality and unintended consequences, then review the evidence with the people closest to the work.
- Define the outcome in language a customer recognises.
- Choose a reversible experiment and name its owner.
- Measure speed, quality, adoption and stewardship together.
- Scale only what earns trust.
Good systems make the right behaviour easier. They offer sensible defaults, explain why a field is needed and provide an escape hatch when reality does not fit. A monthly review should combine a small dashboard with a human conversation about demand, errors, accessibility and the distribution of benefits. Archive decisions, not just numbers, so the organisation compounds judgement over time.
| Signal | Healthy question | Evidence |
|---|---|---|
| Outcome | Are people better served? | Completion and satisfaction |
| Quality | Can we trust the result? | Review and spot checks |
| Adoption | Is it actually used? | Repeat usage |
| Stewardship | Are risks controlled? | Access and incident log |
Premium technology is the calm, dependable layer that helps people make better decisions.
Questions for the next conversation
- Which decision creates the most avoidable rework?
- Where must a human remain accountable?
- What evaluation example is currently missing?
- Which signal would require the AI workflow to stop?

Use this visual as a prompt for discussion: what changed, who benefits, which assumption needs testing, and what evidence would make the next decision safer? A mature team does not treat an image or chart as decoration. It asks what the visual makes easier to notice, what it leaves out, and whose experience should be added before a decision is made. Record the interpretation beside the metric, test it against a real example, and revisit it when the context changes. This simple practice turns a polished article into a useful working session.
Practical AI earns its place by making evidence clearer while keeping responsibility visible. Scale the workflow only when review quality, user confidence and operational value improve together.
Use this visual as a prompt for discussion: what changed, who benefits, which assumption needs testing, and what evidence would make the next decision safer? A mature team does not treat an image or chart as decoration. It asks what the visual makes easier to notice, what it leaves out, and whose experience should be added before a decision is made. Record the interpretation beside the metric, test it against a real example, and revisit it when the context changes. This simple practice turns a polished article into a useful working session.